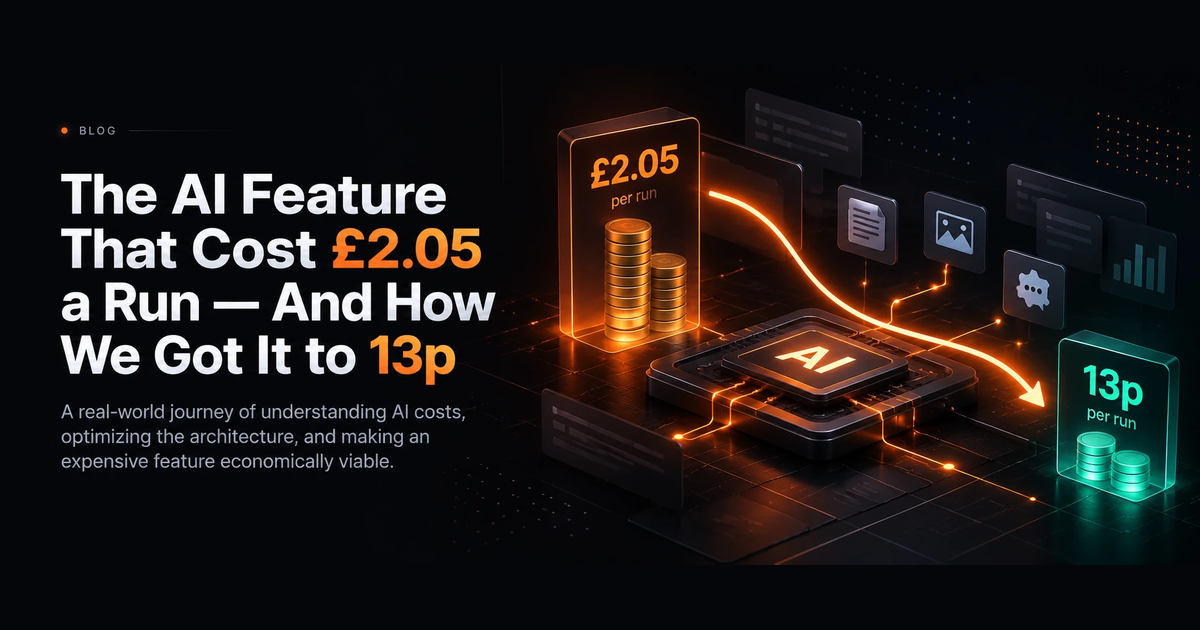
The AI Feature That Cost £2.05 a Run — And How We Got It to 13p
One button researches an organisation on the open web and proposes four things it could do next. The first version worked on the first try. It also cost £2.05 every time someone pressed it. Here is what the measurements actually showed, and the three changes that took it to 13p.
Subhankar Denria
Software Architect · Product Engineer
An organisation clicks one button. The system researches them on the open web, cross-references what it already knows about them, and proposes four specific things they could do next — each with a target, a launch date, a rationale and its sources. One more click turns a chosen idea into a draft, ready to edit and publish.
The whole thing runs in three to five minutes. This is what the user watches while it does:
Every step is a real pipeline stage, not a timed animation. A queued job writes its current step to a row; the page polls it every two seconds. No websockets needed.
That progress list is also the architecture, which is not an accident. Three of those eight steps never touch a model at all — and that split is the reason this post can end with a number instead of an apology.
The One Decision Everything Else Rests On
The obvious way to build this is to hand the whole job to a language model and let it work. That is the expensive, fragile way. The work is actually three different kinds of problem, and each wants a different tool.
Deterministic code
Owns facts
- —Organisation profile and history
- —Calendar dates, from a seeded table
- —Duplicate detection
- —Target clamping against past results
The model
Owns judgement
- —Reading the open web
- —Spotting what is worth acting on
- —Choosing a date from the shortlist
- —Drafting the proposal
The model is never asked to remember something the database already knows.
“Deterministic code owns facts. The model owns judgement.”
We own the organisation data, so profile, history and duplicate detection are plain database queries: instant, free, and incapable of hallucinating. Reading the organisation's website and finding their public presence elsewhere is one model call with server-side web search and fetch — no crawler, no search API key, no HTML parsing to maintain. Calendar dates are facts, so they come from a seeded local table and are merely offered to the model as candidates. A wrong date on a customer-facing card destroys trust in the entire feature.
That split removed most of the risk and most of the build cost. It also made the thing testable: two thirds of the pipeline can be asserted on without any model involved.
Two Model Calls, Not Eight
Call 1 — Research
Server-side web search and fetch, structured JSON out. It takes the organisation's name, website, location and registration number, and returns verified facts — each carrying the URL it was read on — plus inferred opportunities, upcoming events, external presence, and the list of pages it actually visited.
Call 2 — Ideation
No tools. It takes the research blob, the internal performance data, the shortlisted calendar dates, and an explicit list of what the organisation already runs. It returns four proposals.
Why Two Rather Than One
"Give me four different ideas" re-runs only the second call. Nothing is re-searched, so it is fast and cheap. Research is cached against the organisation for 30 days and reused. This one decision is worth about 75% of the running cost in normal use.
The £2.05 Problem
The first version worked on the first try. It also cost £2.05 a run. We measured before optimising, which turned out to matter enormously.
| Run | Input tokens | Output tokens | Searches | Cost |
|---|---|---|---|---|
| 1 | 294,000 | 13,700 | 7 | £1.61 |
| 2 | 453,000 | 12,700 | 2 | £2.05 |
Over 90% of the cost was input tokens. Not reasoning, not output — reading. Look at run 2: five fewer searches than run 1, and 27% more money.
The cause: every page the model fetches stays in the conversation and is re-sent on each subsequent tool-use iteration. We had allowed 40,000 tokens per page across five pages. A typical web page is around 2,500 tokens. We were paying, repeatedly, for headroom nobody used.
“Every instinct said "use a cheaper model". The data said "stop re-sending the same pages". Both helped — but only one was the actual problem, and a week could easily have gone into the wrong one.”
Three Changes
- 1A different model for each stage. Reading pages and extracting facts is extraction work, and a mid-tier model does it well. Deciding which facts are worth acting on is judgement, and stays on the strongest model — ideation costs about 13p either way, so there was never a reason to economise there.
- 2Cap what enters the context. 8,000 tokens per page, three pages instead of five. The single largest lever, and it is a configuration value rather than a code change.
- 3Cache the expensive half. An organisation's profile does not change weekly. Research once, reuse for 30 days, and pay only for the judgement layer after that.
A model per stage
Top tier→Mid tier
Cap the context
40k × 5 pages→8k × 3 pages
Cache the research
Every run→Once per 30 days
The first run for a new organisation still pays for research: £0.51, measured on the third live run at 222,000 input tokens, producing four well-sourced proposals. Every run after that is £0.13.
Bounding the Bill
Cutting unit cost is only half the job. A cost you cannot put a ceiling on is not a cost, it is an exposure.
Usage is capped at two generations per organisation per calendar month. A generation is anything that returns a fresh set of proposals. Refining a proposal, dismissing one, or acting on one is free and unlimited — an organisation that has spent its allowance can still work with what it has.
Because the second generation reuses cached research, the worst case per organisation per month is £0.51 + £0.13 = £0.64. Which means the whole feature has a hard number attached to it:
| Organisations | Absolute monthly ceiling |
|---|---|
| 10 | £6.40 |
| 100 | £64 |
| 500 | £320 |
That is a number that can go on a slide before a single user shows up. Per-run cost is an interesting figure. Maximum monthly exposure is the one that gets a feature approved.
Never Letting the Model Be the Last Word on a Fact
The prompts forbid inventing facts. Prompts are not a control, though — they are a request. Code then enforces the same rules regardless of what comes back.
Fetched web pages are treated as untrusted input throughout — material to report on, never instructions to follow. Structured output means the worst a hostile page can do is fill known fields with nonsense that a human then rejects.
Making a Three-Minute Wait Bearable
The research call is a single request that ran for 210 seconds on one organisation and over 300 on another. As a plain request it gave the progress screen nothing to say for that entire period. So the call is now streamed: each server-side tool call is reported as it happens, and the user sees the real searches and page reads.
Every line is real work. Nothing is invented to fill the gap.
Two details mattered more than expected:
- Web search runs code execution internally to filter results, and those calls carry neither a query nor a URL. Describing them as "nothing" blanked the activity line between real searches, which read as a stall.
- The model thinks for up to a minute before its first search, so the step opens by naming what it is looking up rather than showing an empty line.
Five Things That Cost Us Time
A timeout that was never applied
The job declared its 600-second timeout as a method. The framework reads a property when serialising a job into the queue, and never consults a method. The payload therefore carried no timeout, the worker applied its own 60-second default, and every live run was killed about a minute in — after its searches had already been paid for.
Workers hold the configuration they booted with
A worker started before the API key was added kept serving fixture data for its entire lifetime, with the key sitting right there in the environment file. Any environment change needs a worker restart. So does any deploy.
Structured output rejects constraints you would expect to work
minItems other than 0 or 1, and minimum/maximum on integers, both return errors. Those constraints moved into the prompt and into validation code.
A reset command that destroyed paid-for research
Clearing a usage allowance deleted the run rows — and the cached research lived on those rows. Freeing an allowance quietly threw away real money. It now marks rows instead of deleting them, and the destructive path warns about what it is discarding.
A killed job left the UI spinning
When the worker killed a job, nothing told the run row, so the progress bar belonged to a process that no longer existed. The job now implements the framework's failure hook and marks itself failed immediately.
What I Would Take to the Next Build
- Deterministic code owns facts, the model owns judgement. Everything that can be looked up, should be.
- Do not rebuild what the platform gives you. We nearly wrote a crawler and wired up a search API. Neither was needed — the provider runs both server-side. That decision saved more engineering time than the cost work saved money.
- Measure before optimising. The intuitive fix and the correct fix were different things.
- Design the ceiling, not just the unit cost.
- Make the expensive path the rare path. Caching the research is a bigger lever than any model choice.
Known Gaps
Four, and they are worth stating plainly rather than discovering later:
- No manual research refresh. The pipeline supports forcing one, but nothing in the interface offers it, so an organisation that announces something new mid-month cannot make the system see it until the 30-day cache expires.
- Profile facts and time-sensitive activity share one cache lifetime, despite very different shelf lives.
- Research lives on run rows rather than in a dedicated store, which makes it vulnerable to housekeeping.
- The quality claim rests on one comparison. The cheaper configuration produced specific, well-sourced output, but a single side-by-side is weak evidence. It is being watched, not proven.
“The interesting engineering here was not the prompting. It was working out which parts of the job a model should never have been given in the first place.”
Written by
Subhankar Denria
Software Architect · 25+ products shipped